Ideas Behind GPU Lexer
I made gpu-lexer, a syntax highlighter with no grammars. It’s a tiny model running on WebGPU that looks at source code and guesses what each part is, without being told the language. The whole library is ~28kB.
import { parse } from 'gpu-lexer'

const spans = await parse('source code')
// {
//   type: 'plain' | 'comment' | 'string' | 'number' | 'keyword' | 'type' | 'function' | 'constant' | 'operator'
//   start: number
//   end: number
// }[]
It’s an experiment, and it got more attention than I expected. The lexer itself matters less to me than the ideas that got me there, so that’s what this post is about.
#Find the Problem Someone Already Solved
It started with a chain of whys:
- The bundle is too large, and loading grammars on demand is tricky. Why?
- Because every language needs its own grammar, and there are endless languages. New frameworks and dialects keep appearing, and each one is a grammar nobody has written yet. But do they really need separate rules?
- Not really. Most of the syntax is shared.
var x =,let x =,val x =,auto x =anddef x =are the same idea in different languages, and so are strings, comments, numbers and function calls. A grammar writes that rule again for every language. Could it be written once? - Yes, by learning it instead of writing it. A model can pick up those shared patterns from examples and apply them to languages it has never seen.
Each step digs one layer below the symptom, and by the end the question has changed. It’s no longer “how do I ship grammars efficiently” but “what kind of model can label code without knowing the language?”
That question already has an answer in another field: image segmentation. A segmentation model looks at a photo and labels every pixel as wall, table, laptop, glass or cable. Nobody writes rules for what a glass looks like. The model learns it, and even small ones do it well.
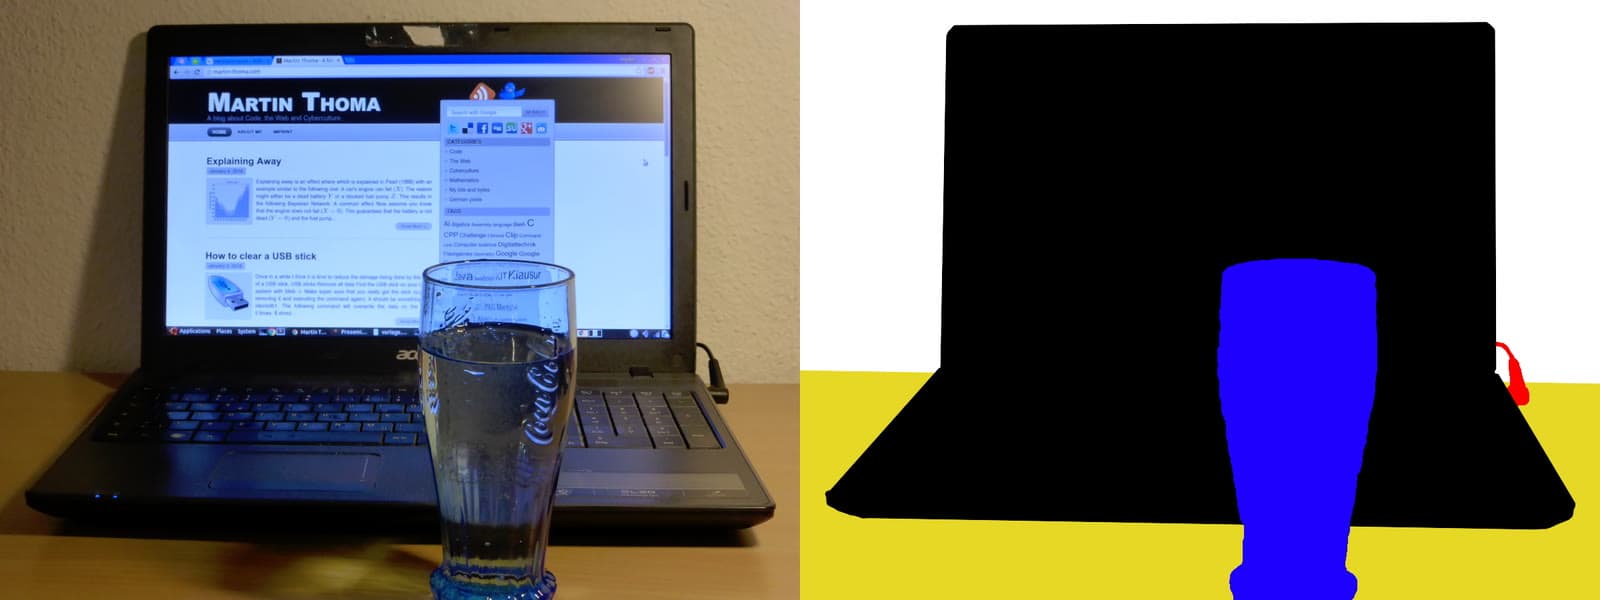 Sidenote: Every pixel gets a class. Photo and mask by Martin Thoma, CC0, via Wikimedia Commons.
Highlighting is the same problem, minus one dimension. Split a piece of code into its smallest parts (words, symbols, spaces) and treat each one as a pixel. Now the source is a 1D image, and highlighting means labeling every pixel as keyword, string, comment and so on. A 2D problem that models have already solved becomes a 1D problem that should be easier.
The analogy also tells you what the model needs. Labeling a pixel takes its neighbors (is this word followed by =) and the whole picture (are we inside a string that opened 200 parts ago). gpu-lexer works the same way. Context flows up a tree to summarize the file, flows back down, and then every part is labeled in parallel on the GPU.
There’s no grammar anywhere in that pipeline. What the model learns are shapes that cross language boundaries, which is why it does reasonably well on languages it never saw in training.
Most hard problems have a solved twin in another field. To find it, you first have to understand your own problem well enough to describe its shape without its jargon.
#Don’t Aim for 100%
A highlighter that gets things wrong sounds useless. But what’s the worst that can happen? A word shows up in the wrong color, and your code still runs. Highlighting is a visual aid, not a compiler, and that gives you room to trade a little accuracy for a lot of everything else. (Rule-based highlighters aren’t perfect either: against Shiki, Prism.js and Highlight.js score 84.1% and 70.1%, and gpu-lexer scores 86.8%.)
In exchange, you get one model that covers every language, at a fraction of Shiki’s ~1MB of grammars. It also finishes a 5.5M-character file in under a second, without blocking the main thread.
You can’t max out all four, and we don’t weigh them equally either. Correctness feels non-negotiable. A slow highlighter is a trade-off, but a wrong one feels like a bug. So most tools treat correctness as the goal and only trade among the other three.
But that weighting is a habit, not a law. For a visual aid, being a little less correct may cost much less than shipping a megabyte of grammars. If the goal had been “always correct”, I would never have started. The dimension everyone treats as fixed is often where the new idea is.
#Treat New Tools Like New Elements
When chemists discover a new element, the first experiments are the obvious ones: what it looks like, what it reacts with. The bigger changes come later, when people start mixing it with everything that already exists. A new element brings a whole set of possible compounds with every element that came before it.
WebGPU is a new element for the web. So far it’s mostly been used for what GPUs are known for: shaders, 3D, and running heavy math computations. Those are the obvious reactions. But a GPU sitting in every browser can do more than graphics. It can also take on ordinary, unglamorous work that has been done on the CPU for decades, like tokenizing code.
The same goes for smaller elements. CSS Anchor Positioning was made for tooltips and popovers. In COBE v2, I used it to fix a long-standing problem: attaching HTML labels to points on a WebGL globe. Now labels simply follow the globe as it spins, and you can style them with plain CSS.
Nobody hands you that list. You have to go through old problems one by one and ask what changes once the new element is in the mix. Most of the time the answer is nothing. Sometimes it’s a 28kB highlighter.
#Toss Out a Brick
There’s a Chinese idiom, 抛砖引玉: toss out a brick to draw out jade. You share something rough so that others share something better.
Within days, people had built their own small models for other jobs on the web:
- gpu-time: turns natural language into dates, ranges and recurrence rules
- gpu-query: turns a search phrase into structured filters
- neural-flexbox: guesses flexbox layout
- gpu-cron: turns natural language into cron expressions
- tinySarf: analyzes Arabic word structure
- gpu-color: turns color descriptions into hex codes
- gpu-font: finds the font in a screenshot
- lexaddr: labels the parts of Spanish addresses
- gpu-pii: flags personal information in text
- gpu-utils: a whole set of them, for citations, emails, logs, Tailwind classes and more
One went the other way and stayed with highlighting: jev-lexer keeps gpu-lexer’s pipeline but swaps the trained model for an LLM.
Most of them have nothing to do with code. What spread wasn’t the code but the idea: a model small enough to ship inside a library can replace a pile of hand-written rules.
I didn’t see any of these coming. Fonts in a screenshot, Arabic word structure, personal information in text: I would never have thought of them myself. That’s why I think a new idea is worth sharing even when it’s rough. If you suspect it can spark other ideas, don’t wait until it’s polished. A finished library gets used. A rough idea gets picked up and turned into things you never imagined.
That was the brick. I’m glad I threw it.